From Performance to Profit: How Unified Experience Management Powers Black Friday Success

Black Friday 2025 is projected to generate over $75 billion in online sales. But here’s the sobering reality: for every second your website is slow or unavailable, you’re not just losing transactions—you’re hemorrhaging revenue, customer trust, and competitive advantage.

The Million-Dollar Stakes of Black Friday

The numbers tell a brutal story. During peak shopping periods:

  • 1 second of downtime can cost large retailers up to $300,000, according to a Gartner study on IT downtime costs.
  • 53% of mobile users abandon sites that take longer than 3 seconds to load, as reported by Google Research on mobile site performance.
  • A single performance incident during Black Friday can wipe out an entire quarter’s worth of customer acquisition efforts, according to Forrester Research.

When your infrastructure buckles under 10x normal traffic, the consequences extend far beyond immediate lost sales. Customer lifetime value evaporates. Brand reputation takes years to rebuild. And your competitors? They’re capturing the customers you worked all year to attract.

Why Point Tools Fail When It Matters Most

Most organizations approach Black Friday with a patchwork of disconnected tools:

  • Testing teams rely on platforms like LoadRunner or k6 to simulate user load and validate scalability. But these tools operate in isolation, offering no visibility into how that load impacts downstream systems or real users in production.
  • DevOps teams monitor infrastructure through solutions such as AppDynamics, Datadog, or Dynatrace. While powerful for system metrics, they often lack direct correlation to user experience or business KPIs.
  • Application teams dig through log analysis tools like Splunk, Elastic APM, or New Relic to trace issues post-incident. However, the process is manual, time-consuming, and reactive rather than proactive.
  • Business stakeholders may now have dashboards and reports, but they still struggle to interpret the complete context—how application performance, infrastructure stability, and user experience converge to affect revenue in real time.

This fragmentation creates dangerous blind spots. When a checkout failure surfaces at 2 AM on Black Friday, your teams waste precious minutes:

  • Correlating data across multiple dashboards
  • Debating whether it’s a frontend issue, API bottleneck, or database constraint
  • Manually stitching together incomplete pictures of user impact
  • Escalating through siloed teams while revenue bleeds

The result? Mean Time to Resolution (MTTR) stretches from minutes to hours. By the time you’ve identified and fixed the issue, thousands of abandoned carts have already cost you millions.

The Unified Platform Advantage: Performance Meets Profit

The shift from point tools to unified experience management isn’t just operational efficiency—it’s business resilience. Here’s what changes when you consolidate testing, monitoring, service virtualization, and AI-driven insights into a single platform:
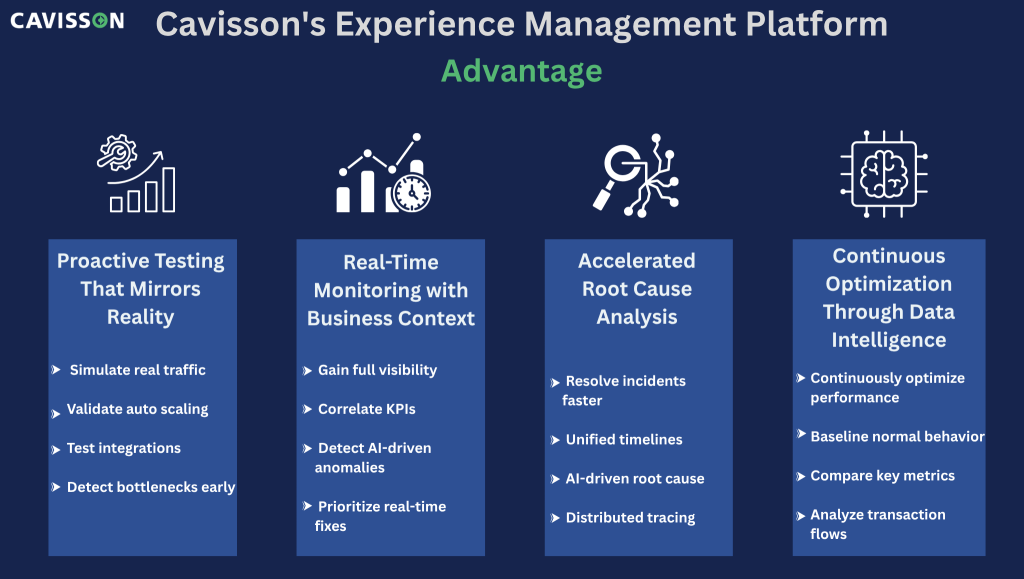
1. Proactive Testing That Mirrors Reality

Pre-Black Friday load testing isn’t about hoping for the best. With the performance testing module of Cavisson’s Experience Management Platform, you can:
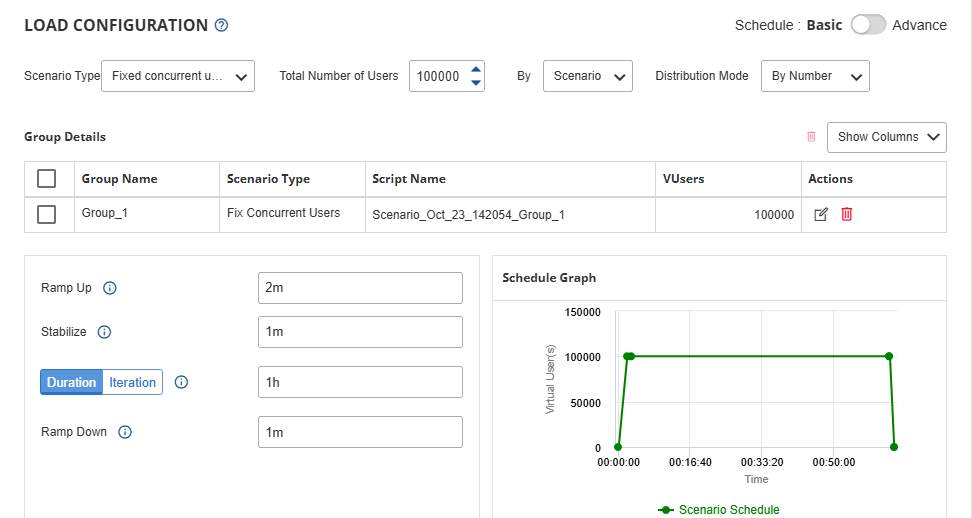
  • Simulate millions of concurrent users across complex transaction flows
  • Test third-party payment gateway integrations without depending on vendor availability (via service virtualization)
  • Identify breaking points in your infrastructure before customers do
  • Validate that your auto-scaling policies actually work under real-world conditions

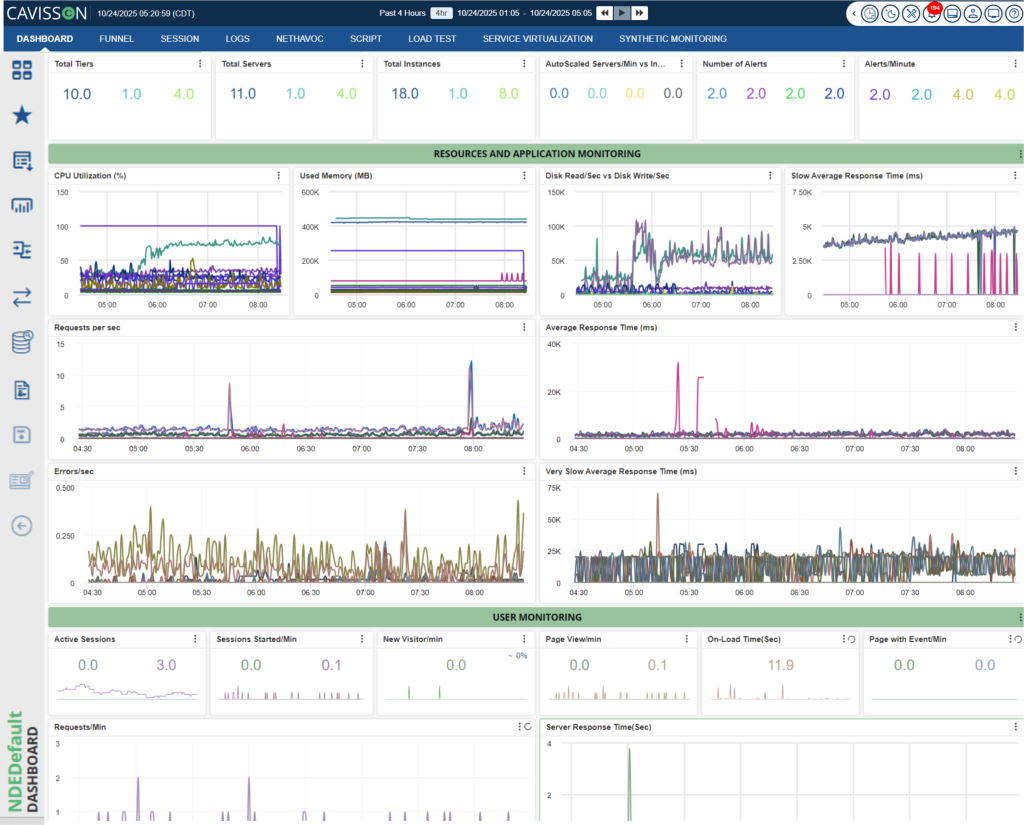
2. Real-Time Monitoring with Business Context

When traffic surges, you don’t need more metrics—you need intelligent insights. An experience management platform provides:

  • End-to-end transaction visibility: From browser click to database query, see exactly where slowdowns occur
  • Business KPI correlation: Instantly understand how a 500ms API delay impacts conversion rates
  • Automatic anomaly detection: AI identifies unusual patterns before they cascade into outages
  • User experience scoring: Know which customer segments are affected and prioritize fixes accordingly
3. Accelerated Root Cause Analysis

The power of unification becomes clearest during incidents. Instead of jumping between tools:
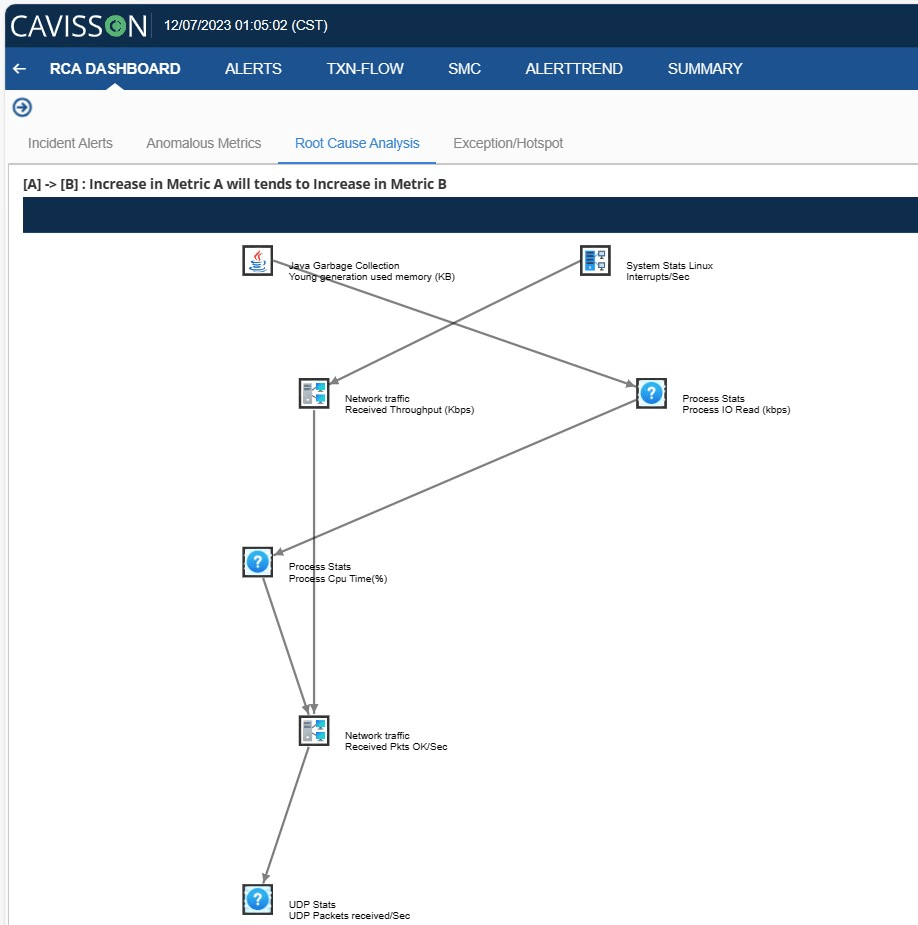
  • A single timeline correlates load test results, production metrics, and deployment events
  • Distributed tracing automatically maps requests across microservices
  • AI-powered diagnostics suggest probable causes based on historical patterns
  • One dashboard gives every stakeholder—from developers to executives—the visibility they need

4. Continuous Optimization Through Data Intelligence

Beyond firefighting, unified platforms enable continuous performance improvement:

  • Baseline normal behavior to detect degradation early
  • Compare pre-production test results with live production metrics
  • Identify optimization opportunities through transaction flow analysis
  • Build a knowledge base of performance patterns that improve year over year

Real-World Impact: From Chaos to Control

Consider a major retail client who partnered with Cavisson before last year’s Black Friday. Previously reliant on disconnected monitoring and reactive firefighting, they faced a critical decision: continue with the status quo risk or transform their approach.

The Challenge:

  • Checkout completion rates dropped to 62% during the previous peak events
  • Average MTTR for performance incidents: 47 minutes
  • No clear visibility into third-party service impacts
  • Testing cycles took weeks due to dependency constraints

The Unified Approach: Using Cavisson’s integrated platform, they implemented:

  • Comprehensive load testing with service virtualization for all payment gateways
  • Real-time monitoring across 200+ microservices
  • AI-driven alerting with automatic root cause suggestions
  • Single-pane visibility for cross-functional war rooms

The Results:

  • MTTR reduced to 8 minutes: Unified visibility eliminated diagnostic guesswork
  • Checkout rates improved to 94%: Proactive testing identified and resolved bottlenecks pre-launch
  • Zero revenue-impacting outages: During the highest traffic event in company history
  • 73% reduction in escalations: Issues resolved before customers noticed

More importantly, their performance team transitioned from reactive crisis management to proactive optimization, continuously improving conversion rates throughout the holiday season.

Get Performance-Ready Before Peak Traffic Hits

Black Friday success isn’t determined on the day itself—it’s won in the weeks of preparation that precede it. The question isn’t whether you can afford to invest in unified experience management. It’s whether you can afford not to.

As traffic projections climb and customer expectations intensify, the gap between resilient businesses and vulnerable ones widens. Organizations that embrace end-to-end visibility, AI-driven insights, and proactive testing position themselves not just to survive peak season but to dominate it.

Don’t wait for downtime to expose your blind spots.

Cavisson’s unified platform combines enterprise-grade load testing, real-time application monitoring, service virtualization, and AI-powered analytics—giving you complete visibility and control over digital experiences when it matters most.

Ready to turn Black Friday from a risk into an opportunity?

Click for schedule your performance readiness assessment

Let’s ensure your infrastructure is as ambitious as your revenue targets.
NetHavoc by Cavisson Systems: Transform System Reliability Through Chaos Engineering

Why Your Production Systems Need Chaos Engineering?

In today’s hyper-connected digital landscape, system downtime isn’t just an inconvenience—it’s a business-critical disaster. A single minute of downtime can cost enterprises thousands of dollars, erode customer trust, and damage brand reputation. The question isn’t whether your systems will fail, but how well they’ll survive when they do.
(more…)

Injecting Havoc to Build Resilient Systems: A Deep Dive into Failure Scenarios

Injecting Havoc to Build Resilient Systems: A Deep Dive into Failure Scenarios

Modern digital businesses thrive on speed and reliability. Yet, history shows us that no system is immune to failure. A single point of exhaustion—whether CPU, memory, network, or storage—can bring billion-dollar services to a halt. This is where chaos engineering steps in: by deliberately injecting havoc into systems, teams discover weaknesses before real customers do.

In this blog, we’ll explore the four pillars of Chaos Engineering—Starve Application, State Change, Network Assaults, and Application Disruption. Alongside, we’ll revisit real-world outages that underline why preparing for the worst is the smartest strategy.

(more…)

How to Achieve Peak Performance Testing Across Industries

How to Achieve Peak Performance Testing Across Industries
In today’s hyperconnected digital landscape, application performance can make or break a business. From e-commerce platforms handling Black Friday traffic surges to banking systems processing millions of transactions daily, every industry faces unique performance challenges that demand specialized testing approaches. At Cavisson Systems, we’ve witnessed firsthand how organizations across diverse sectors achieve peak performance testing results with the right strategy and tools.

The Universal Challenge: Performance at Scale

Regardless of industry, modern applications must deliver consistent, reliable performance under varying loads. However, the definition of “peak performance” differs dramatically across sectors:
  • Financial Services require sub-second response times for trading platforms and zero downtime for critical banking operations
  • E-commerce platforms need to handle traffic spikes during sales events without cart abandonment or revenue loss
  • Healthcare Systems demand reliable performance for life-critical applications and patient data management
  • Telecommunications providers must ensure network services perform flawlessly under peak usage scenarios
  • Manufacturing systems require real-time performance monitoring for IoT devices and supply chain applications
(more…)

Service Virtualization for Scalable Testing: How Enterprise Teams Test the Untestable

Service Virtualization for Scalable Testing: How Enterprise Teams Test the Untestable
In today’s interconnected digital landscape, enterprise applications rarely operate in isolation. They depend on complex ecosystems of backend services, third-party APIs, legacy systems, and external dependencies that can make comprehensive testing a logistical nightmare. How do you test an application when critical dependencies are unavailable, unstable, or prohibitively expensive to access during development cycles? The answer lies in service virtualization – a transformative approach that’s revolutionizing how Fortune 500 companies approach quality assurance and performance testing.
(more…)

Unlocking the Power of 1000x QPS: How Query Performance Transforms Modern Observability

Unlocking the lower of 1000x QPS
In the rapidly evolving landscape of distributed systems and microservices, the ability to query and analyze observability data in real-time has become a critical differentiator. At Cavission Systems, we’ve engineered our platform to deliver unprecedented query performance, achieving 1000x higher Queries Per Second (QPS) than traditional observability solutions. But what does this mean for your engineering teams, and why should QPS be a primary consideration when choosing your next observability platform?
(more…)

Ultra-High Data Ingestion Enhances Observability

Ultra-High Data Ingestion Enhances Observability
In today’s hyper-connected digital landscape, enterprises face an unprecedented challenge: how to maintain complete visibility into increasingly complex systems while managing exponentially growing data volumes. Traditional observability platforms have long operated under a fundamental constraint—they sacrifice data completeness for performance, forcing organizations to choose between comprehensive insights and system responsiveness. This trade-off is no longer acceptable. Modern enterprises need full-fidelity observability that captures every signal, every anomaly, and every performance nuance without compromise. This is where ultra-high data ingestion capabilities become not just an advantage, but a necessity.
(more…)

How Integrated Observability Transforms Performance Testing

How Integrated Observability Transforms Performance Testing
In today’s digital landscape, application performance directly impacts business outcomes. A single second of delay can cost enterprises millions in lost revenue, while poor user experiences drive customers to competitors. Yet despite this critical connection, many organizations still approach performance testing and observability as separate disciplines, creating blind spots that can prove costly. Recent industry surveys reveal a growing recognition that comprehensive observability—integrating User Experience (UX) monitoring, Application Performance Monitoring (APM), and log analysis—is essential for effective performance testing. When we asked performance engineers and DevOps teams about their observability strategies, the results painted a clear picture of industry evolution and persistent challenges.
(more…)

Bridging the Gap: How User Experience Monitoring Transforms Release Management

How User Experience Monitoring Transforms Release Management
In today’s rapidly evolving digital landscape, delivering new features while maintaining an exceptional user experience is a constant challenge for development teams. The integration of User Experience (UX) monitoring into release management processes has emerged as a pivotal strategy to navigate this delicate balance.

Understanding the Importance of UX Monitoring

User expectations are higher than ever. A delay of just one second in page response can lead to a 7% reduction in conversions, and according to research by Google, if an app fails to load within three seconds, up to 53% of users abandon it. These statistics underscore the critical role of UX in user retention and business success.
(more…)

Optimizing Application Performance: Key Insights from Industry Testing Practices

How combining application monitoring with performance testing creates proactive performance management?

Optimizing Application Performance: Key Insights from Industry Testing Practices

Introduction

In today’s digital landscape, application performance is directly tied to business success. Our recent industry survey revealed fascinating insights into how organizations approach performance testing and infrastructure monitoring. This blog explores the challenges, strategies, and success stories from companies that have mastered the art of performance optimization through integrated monitoring and testing approaches.

Survey Results: The Performance Monitoring Landscape

Our recent polling of IT professionals revealed several interesting trends in application performance monitoring and testing:

What is your biggest challenge when monitoring application performance during load tests?

Key findings:
  • 20% struggle with correlating user experience to backend performance
  • 60% identified service bottlenecks as their primary challenge
  • 15% face infrastructure scaling issues
  • 5% find it difficult to analyze response time degradation patterns
👉 Takeaway: Majority of teams struggle with identifying service bottlenecks, while correlating user experience and backend performance remains a significant blind spot.
(more…)